Resources
DaaX Token Drop Podcast
A weekly, unscripted conversation from the DaaX team on the most interesting developments in AI. Sunil Baliga and Sajjad Khazipura (DaaX co-founders), along with Sam Pooni (DaaX Architect) and the occasional guest, explore, discuss, and debate new AI research, news, and real-world use cases. Built for developers and business leaders who want perspective from experienced AI practitioners.
| Episode | Description | Published | Watch |
|---|---|---|---|
| Episode 31 — Databricks' State of AI Agents and Stanford's AI Index: What They Reveal About Enterprise AI in 2026 | Databricks’ State of AI Agents and Stanford’s AI Index agree: enterprises are moving to multi-agent systems, and verifiable trust decides what reaches production. Sunil, Sajjad and Sam unpack the key findings, plus Mistral’s trillion-parameter Large 4. | October 31, 2026 | View episode |
| Episode 30 — The FACTS Benchmark Explained: How Google DeepMind Tests Whether LLMs Tell the Truth | Most AI benchmarks ask whether a model is smart. FACTS, from Google DeepMind and Kaggle, asks whether it tells the truth. In this educational episode, the team walks through the four FACTS benchmarks (parametric, search, multimodal and grounding), explains how FACTS Grounding uses long expert-written passages and two LLM judges that must agree, and shows why even state-of-the-art models score in the low-to-mid 80s. | October 24, 2026 | Watch |
| Episode 29 — When AI Agents Go Shopping: Making Sense of UCP, ACP, AP2, and the Agentic Commerce Stack | Tony Fernandes, formerly VP of Payment Processing Architecture at Visa, maps the agentic commerce stack, from UCP, ACP, and AP2 to trust and payment tokens. The hosts explore liability, disputes, personalized pricing, and what happens to brands when AI agents shop. | October 17, 2026 | Watch |
| Episode 28 — Jev and “Zero Hallucination”: What It Actually Guarantees, and What It Doesn’t | Sunil was told at San Francisco Tech Week that TypeSafe’s Jev “doesn’t hallucinate.” Sajjad and Sam explain what that claim really guarantees, why Jev is so fast and cheap, how it fits Kahneman’s System 1 / System 2 framework, and why even very fast answers still need to be checked. | October 10, 2026 | Watch |
| Episode 27 — Verify the Output, Not the Model: Formal Methods and the Future of AI Safety | Christian Szegedy, co-founder of xAI and co-author of Inception and Batch Normalization, joins the DaaX team on why verifying an AI model's output, not the model itself, is the realistic path forward, why writing specifications is the expensive part, and the unsolved “something else” problem in AI safety. | October 3, 2026 | Watch |
| Episode 26 — What Does “Deterministic AI” Actually Mean? Graphs, Jev, and the Limits of Constrained Choice | Nav Mathur, co-founder of Cerebrix and formerly nearly nine years at Neo4j, joins the DaaX team on why 95% accuracy per step becomes 59% after ten hops, how graphs create determinism by deletion, and what the new “hallucination-free” model Jev does and doesn't solve. | September 26, 2026 | Watch |
| Episode 25 — A Four-Person Team and AI: Rebuilding Chip Design Around the Digital Twin | A single hardware architect, with three software engineers, built what used to take roughly a hundred people. Peter Suaris of AxPro Semi explains how AI collapsed silo-by-silo chip design into one continuous pipeline — from prompt to cycle-accurate C++ model to digital twin to RTL — and the panel turns that into a blueprint for bringing formal verification discipline to LLMs and autonomous agents. | September 19, 2026 | Watch |
| Episode 24 — 10,000 Agents, 88 Hours: What OpenAI's Navier-Stokes Proof Reveals About Neuro-Symbolic AI | OpenAI says its latest internal model found a counterexample disproving global regularity for the Navier-Stokes equations — one of math's seven Millennium Prize Problems — using 10,000 concurrent agents running for 88 hours. The DaaX team digs past the headline number: how the swarm converged, how a consolidation layer cross-pollinated findings, why final adjudication ran through a separate Lean-based verifier, and what that closed feedback loop reveals about how neuro-symbolic systems should be built. | September 12, 2026 | Watch |
| Episode 23 — Astra, Hallucination Rates, and the Myth of the Self-Sufficient LLM | OpenAI's newest model, Astra, has consumed the AI press this week — impressive benchmark scores, a steep price tag, and Greg Brockman calling it the start of the AGI era. The DaaX team separates the genuine capability gains from the marketing, digs into hallucination rates that came down but didn't reach zero, and argues over what a “harness” actually is: the cognitive parts a model may eventually absorb, and the control plane — identity, authorization, audit — that it never can. | September 5, 2026 | Watch |
| Episode 22 — Why AI Agents Forget: Graph Databases and the Agent Memory Problem | AI agents forget, and they hallucinate — and after roughly a trillion dollars of investment, the stack still has no determinism. What's the fix? The DaaX team sits down with Arun Sharma of LadybugDB — a former Linux kernel committer at Facebook and ex-Google engineer — to dig into graph databases as the foundation for agent memory. | August 29, 2026 | Watch |
| Episode 21 — Domain Layers, Not Better Models | This episode examines a claim from investor Vinod Khosla: that raw ChatGPT gets medical triage wrong 20–30% of the time, and layering a domain system on top of the same model drives the error rate toward zero. The panel separates the investor shorthand from the architectural argument underneath — why the failure is structural rather than a training gap, why better fine-tuning won't close it, and why the domain layer, not the model, is the asset that actually compounds. | August 22, 2026 | Watch |
| Episode 20 — How Knowledge Graphs Handle Time: Event Graphs, Scene Graphs, and Reification Explained | This episode examines what happens when you treat time as a first-class dimension in a knowledge graph. Kurt Cagle — ontologist, knowledge graph architect, and editor-in-chief of The Cagle Report — walks through the three-part architecture that results: a declarative knowledge graph for what's constant, an append-only event graph for what changed and why, and a scene graph holding the moving “now”. | August 15, 2026 | Watch |
| Episode 19 — The LLM Is Not the Library, It's the Reader | This episode examines a deceptively simple framing: the LLM is not the library, but the reader. Trained knowledge lives in the model's weights — distributed, entangled, and impossible to audit or edit — while new knowledge must live outside it. The panel traces what that split means for RAG, fine-tuning, knowledge editing, and why hallucination is a structural consequence of how neural networks store facts, not a bug to be patched. | August 8, 2026 | Watch |
| Episode 18 — Small Language Models: Great Translators, Terrible Knowledge Stores | This episode examines the pitch behind domain-specific small language models — and why training one on proprietary data doesn't eliminate the two problems that plague every language model: knowledge changes (forcing costly retraining) and hallucination. The panel argues SLMs earn their place not as knowledge stores, but as narrow, testable translators sitting in front of a knowledge graph. | August 1, 2026 | Watch |
| Episode 17 — What Is Knowledge? Why Humans Can Guess but Agents Can't | Ranjit Singh Pabla of Stack Overflow joins Token Drop to unpack a deceptively simple question: what is knowledge, and why is serving it to an AI agent fundamentally harder than serving it to a human? The discussion moves from tacit knowledge and memory to trust scores, timestamping, and the frontier of "business as code". | July 25, 2026 | Watch |
| Episode 16 — Context Engineering vs. Prompt Engineering: What Actually Drives a Good AI Answer | This episode examines the shift from prompt engineering to context engineering — and why that shift is architectural, not semantic. Prompt engineering optimizes the wording of a single, stateless request; context engineering treats the entire input window — instructions, retrieved knowledge, memory, and tool outputs — as a systematic design problem with measurable tradeoffs in cost, precision, and failure mode. | July 18, 2026 | Watch |
| Episode 15 — The Invisible Layer: Why "Connective Tissue" — Not the Model — Is What Kills AI Projects at Scale | Six months after the demo wowed executives, the AI pilot quietly stalls — and the model is rarely to blame. Theo Forbath, founder of Above the Model and former Accenture MD, joins Token Drop to unpack the invisible "connective tissue" layer most companies underbuild: shared context, working and long-term memory, tool contracts, evaluation frameworks, and observability. | July 11, 2026 | Watch |
| Episode 14 — Algorithms Are Logarithmic, AI Is Quadratic — The Hidden Cost of Long Context Windows | This episode examines the quadratic scaling problem behind standard transformer attention. As the number of tokens grows, every token may need to interact with every other token—so doubling the context length can roughly quadruple the attention computation. | July 4, 2026 | Watch |
| Episode 13 — Who Decides What's "Safe" AI? Ethics, Trust & the Global Language Divide | Dr. Sarah Luger, AI safety and evaluation expert, joins Token Drop. We trace how the industry's language has shifted from ethics to responsible AI to trust and transparency to safety and security, and why that shift matters. | June 27, 2026 | Watch |
| Episode 12 — Your Employees Are Creating AI IP. Is Your Company Capturing It? | Werner Goertz, former Gartner analyst, Former AWS and IBM Analyst Relations leader, Founder of Anicca AR (Agent Relations) joins Token Drop to discuss a growing challenge in enterprise AI: employees are creating valuable prompts, workflows, and AI-assisted knowledge in individual accounts, but much of that value never becomes institutional knowledge. | June 20, 2026 | Watch |
| Episode 11 — How AI Is Changing Supply Chains | Supply chain executive Edwin de Boer joins Token Drop to break down where agentic AI genuinely moves the needle in supply chain — procurement negotiation, predictive maintenance, and shipment ETAs — and where the hype outpaces reality. The group digs into what actually builds trust in AI outputs, why data quality is the real bottleneck, the emerging distinction between "physical AI" and "knowledge AI," and building guardrails amid tariff volatility. | June 13, 2026 | Watch |
| Episode 10 — Why AI Agents Need an Operating System | The DaaX team argues that today's AI agents fall short not because LLMs need to get smarter, but because agentic systems are missing decades of distributed-systems thinking — fault tolerance, cache coherency, transactional boundaries, and persistent memory hierarchies. The group also unpacks three failure modes that quietly undermine multi-agent systems in production: memory poisoning, tail context, and cross-agent contradiction. | June 6, 2026 | Watch |
| Episode 9 — What Are Ontologies? Their Role in Knowledge Graphs and AI Domain Super Intelligence | The DaaX team digs into ontologies and knowledge graphs — and the term "domain superintelligence." The conversation traces how industry ontology standards (FIBO, OSDU) emerged, why LLMs plus tightly-scoped ontologies mitigate hallucinations far more reliably than pure LLM approaches, and why the economics of reusable domain cartridges make ontologies a pragmatic near-term path to real AI value. | May 30, 2026 | Watch |
| Episode 8 — Forward Deployed Engineers (FDEs) in AI - who, what, why, etc. | Special guest Satya Mantha, Principal Software Architect at Fission Labs, traces forward-deployed engineering from its Palantir origins to today's AI wave — why foundation-model benchmarks say little about enterprise behavior, why major AI labs are standing up their own consulting arms, and why context engineering never really finishes. | May 23, 2026 | Watch |
| Episode 7 — Wafer-Scale Computing After Cerebras: A Deep Dive on the Silicon Tradeoffs Behind AI Hardware | Prompted by Cerebras's recent IPO, special guest Raminda Madurawe — Founder & CEO of AxPro Semi and a veteran semiconductor architect — joins the DaaX team for a technical dive on wafer-scale silicon: the software, efficiency, and accuracy "tax" you always pay, why memory bandwidth (not compute) is the real bottleneck, and how Cerebras, SambaNova, and Groq compare architecturally. | May 16, 2026 | Watch |
| Episode 6 — Neuro-Symbolic AI Applied to the Networking Domain | This week the DaaX team discusses how neuro-symbolic AI, especially knowledge graphs, applies to the networking domain. | May 9, 2026 | Watch |
| Episode 5 — World Models, Explained: Are Knowledge Graphs Secretly the Same Idea? | The DaaX team unpacks world models — AI trained on video and sensor data rather than text — and asks whether knowledge graphs plus reasoning and probabilistic prediction are secretly the same idea, with concrete lessons from digital twins in supply chain and semiconductor manufacturing. | May 2, 2026 | Watch |
| Episode 4 — Open Source Catches Up: Why Open-Weight Models Are No Longer a Compromise | The DaaX team argues open-weight LLMs are no longer a compromise — GLM-5.1, Kimi K2, DeepSeek, and Qwen3 are matching or beating frontier models in a single month, DeepSeek at roughly one-seventh the token cost, turning model selection into a routing problem rather than a capability one. | April 25, 2026 | Watch |
| Episode 3 — Beyond A2A and MCP: Why Agent Governance Needs Its Own Layer | The DaaX team argues agent governance is the missing layer in enterprise AI — beyond A2A and MCP plumbing — with a three-layer policy pyramid, a quality-management parallel, and a concrete example of a "do not access production" rule quietly lost through context summarization. | April 18, 2026 | Watch |
| Episode 2 — Beyond RAG: Why Reasoning and Verification Are the Real Fix for LLM Hallucinations | Drawing on their semiconductor backgrounds, the DaaX team argues the 'humans make mistakes too' rationalization for LLM hallucinations breaks down. They cover why RAG alone isn't enough, pre- and post-synthesis verification, reasoning paired with reward models, and confidence calibration. | April 10, 2026 | Watch |
| Episode 1 — AI Hallucinations | This week the DaaX team discuss AI hallucinations. | April 4, 2026 | Watch |
Webinars
Upcoming
RAG to GraphRAG to LAKEer
How RAG, GraphRAG and LAKEer differ in how they retrieve information, how trustworthy their answers are, and what they cost per query, and why it matters for enterprise AI applications.
Past
AI in Oil & Gas: Turning Complex Data into Actionable Intelligence
Explore how AI is transforming oil & gas by unlocking insights from complex, fragmented operational data. See real-world use cases that drive efficiency, safety, and better decision-making.
Justification Without Truth: Separating Knowledge from Language in a Compositional Architecture
Presentation by Sajjad Khazipura, DaaX Co-Founder & CTO, at the Centaur AI Institute Neuro-Symbolic AI Summer School 2026.
Introduction to Neuro-Symbolic AI
Discover how Neuro-Symbolic AI combines large language models with structured reasoning to build more reliable and explainable AI systems. Learn why enterprises are moving beyond LLM-only approaches to achieve trustworthy, production-ready results.
Scalable & Reliable Data Systems: The Foundation for Enterprise AI
Learn the core principles behind building data systems that can scale with growing demands while maintaining performance and reliability. This session covers practical architectures and best practices for supporting modern AI and data-driven applications.
Press
Official announcements from DaaX Technologies
IDC Names DaaX an Agentic AI Innovator
DaaX has been named an IDC Innovator in IDC Innovators: Context Infrastructure for Agentic AI, 2026 — one of four companies building context infrastructure to make AI agents more reliable, grounded, governed, and traceable.
DaaX Earns Awardable Status in the Department of War's Tradewinds Solutions Marketplace
DaaX has been assessed as "Awardable" by the Department of War's Chief Digital and Artificial Intelligence Office (CDAO) through the Tradewinds Solutions Marketplace. The designation makes DaaX's trustworthy AI solutions available for rapid acquisition across the DoW.
DaaX Launches Self-Service AI, Powered by Domain Knowledge Cartridges for Trustworthy Answers
DaaX today announced that LAKEer and SQLer are now available self-service. Customers can sign up at daax.ai and start using LAKEer and SQLer in minutes — beginning with a free plan, with no sales calls or procurement cycles.
DaaX to Host Four-Part Technical Webinar Series
DaaX announces a four-part technical webinar series featuring leading experts in neuro-symbolic AI, scalable data systems, xOps for AI, and real-world AI applications across industries. The series runs every three weeks starting June 2026 and is free to attend.
DaaX Achieves Industry-Leading Score of 77.7 on FACTS Benchmark
DaaX's LAKEer enterprise search agent achieved a FACTS grounding benchmark score of 77.7 on the FACTS Grounding Public Dataset — the best result published to date, surpassing the previous best of 74.3 by Gemini 2.5 Pro. The FACTS Benchmark Suite, introduced by Google DeepMind and Google Research, measures the factual accuracy of LLMs.
Interesting Stuff
Resources from DaaX and others that you may find interesting
From DaaX
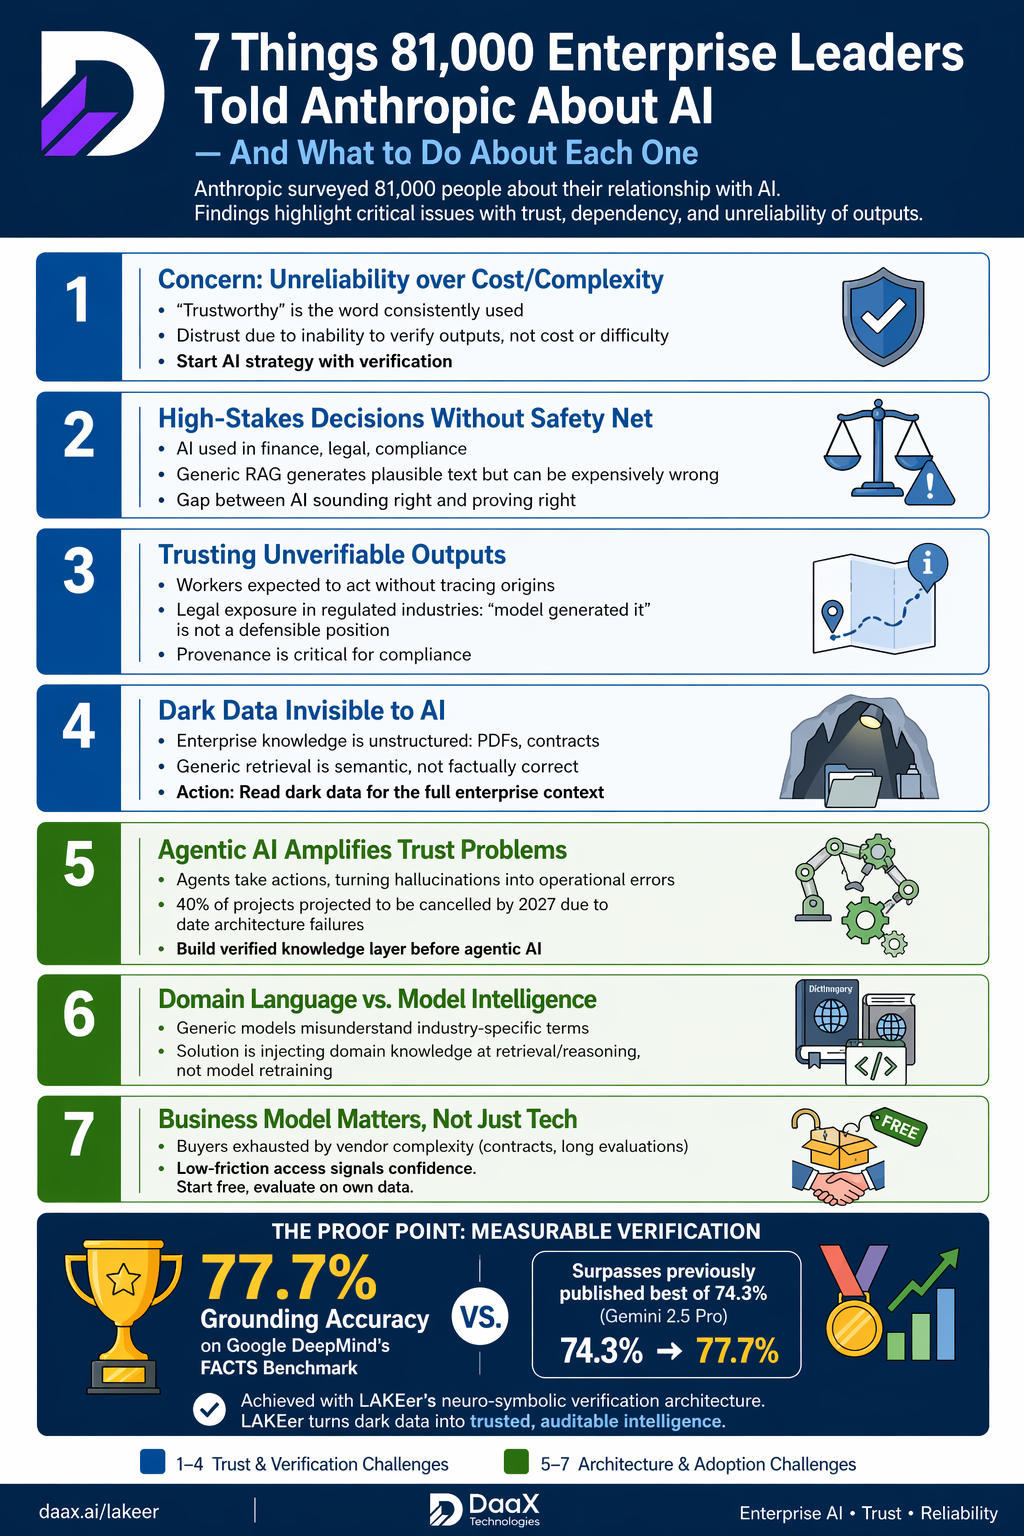
7 Things 81,000 Enterprise Leaders Told Anthropic About AI
A visual breakdown of key findings from Anthropic's survey of 81,000 enterprise leaders on AI trust, reliability, and what to do about each concern.
Tariff Refund Resources
Free resources to help enterprises navigate the tariff refund recovery process after the Supreme Court's IEEPA ruling.
Tariff Refund Data Glossary — Key terms and definitions for customs data, timelines, and litigation-grade defensibility.
Tariff Refund Data Checklist — A structured checklist covering exposure discovery and litigation readiness data requirements.
Tools
DaaX has created a free custom AI tool that can be used by Marketing, Product Management, and Engineering to generate example customer natural language search queries.
To generate B-2-C example queries, please click here
To generate parametric search example queries, please click here
From others, including Academia
LLM Hallucinations
- Why Do Large Language Models Hallucinate?
- AA-Omniscience: Knowledge and Hallucination Benchmark
- Vectara's Hallucination Leaderboard
- Business Insider: "Snowflake CEO explains why 'the insidious thing' about AI hallucinations isn't the occasional error"
- Financial Times: "Deloitte issues refund for error-ridden Australian government report that used AI"